Sudarshana ML — compiled for the Vishwakarma. Hallucination-free by design.
One compiler, one runtime, one instruction set. The Sudarshana framework lowers models straight onto Vishwakarma silicon — no glue, no abstraction tax, no third-party stack. Every inference is verified against a formal bound before it is returned; what cannot be proven is refused.
- Graph compilervw-graph
- Sparse runtimevw-sparse
- On-device quantizervw-quant
- Fleet telemetryvw-signal
- 01 · Compile
Your model is lowered by vw-graph into a closed set of verified Vishwakarma kernels. No interpreter, no escape hatches.
- 02 · Schedule
The sparse runtime places work across the 4-topology NPU with static, deterministic scheduling — latency is a property of the graph, not the queue.
- 03 · Verify
Every inference is checked against a formal bound computed at compile time. Precision drift and out-of-distribution inputs are caught before the answer leaves the chip.
- 04 · Return or refuse
If the bound holds, the answer is returned with its proof attached. If it does not, the system says so — it never guesses.
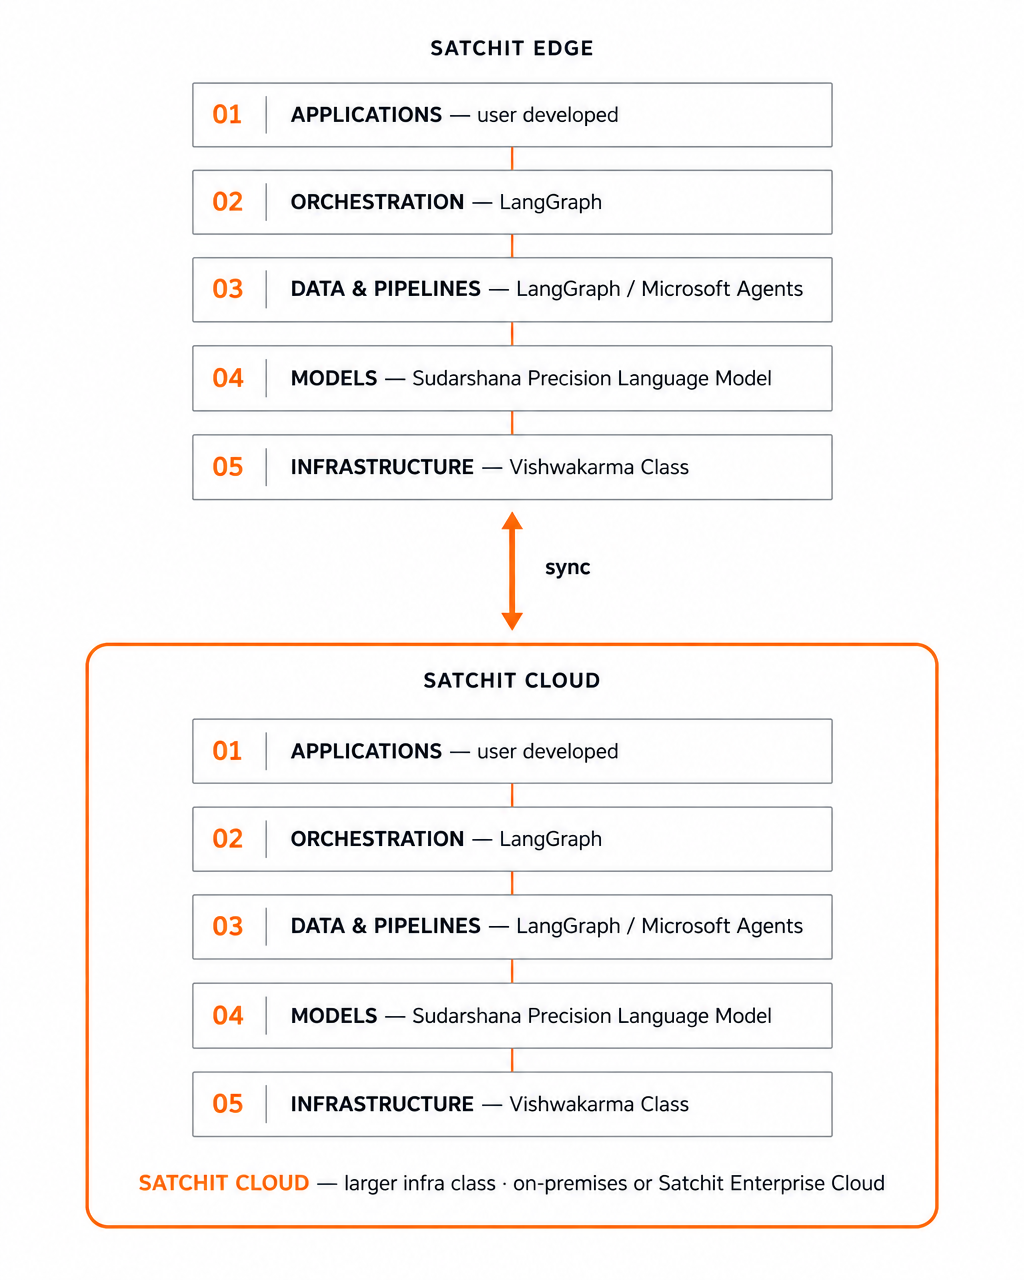
The five layers of the AI Edge — applications, orchestration, data & pipelines, models, infrastructure — mirrored by the same five layers in the cloud, synced both ways.